Simulation restoration · source footage 4×. Real-robot restoration · source footage 2×, motion smoothed for display. These are independent trials.仿真恢复:原片 4 倍速。实机恢复:原片 2 倍速,含展示用运动平滑。两段为独立试验。
Research title研究题名
Toward Whole-Body Intelligence through an Iterative World Action Model for Precise Scene Restoration面向全身智能:通过迭代世界动作模型实现精细场景恢复
A mobile manipulator restores object positions to match a visual reference. Learned docking connects base placement to manipulation outcomes, and an iterative World Action Model refines future predictions before generating arm actions.移动操作机器人根据视觉参考恢复物体位置。学习式停靠将底盘位置与操作结果联系起来,迭代世界动作模型则在生成机械臂动作之前细化未来预测。
More real-robot excerpts更多实机片段
A continuous grasp, transfer and release excerpt from the real-robot demonstration.实机演示中的连续抓取、搬运与释放片段。Source footage: 2× playback; motion smoothed for display.原片为 2 倍速播放,并经运动平滑用于展示。
The mobile base approaches a manipulation pose before the arm acts.机械臂行动之前,移动底盘先靠近操作位置。Source footage: 2× playback; motion smoothed for display.原片为 2 倍速播放,并经运动平滑用于展示。
A yellow-cup restoration excerpt from the additional real-robot trials.来自额外实机实验的黄色杯子恢复片段。Source footage: 2× playback; motion smoothed for display.原片为 2 倍速播放,并经运动平滑用于展示。
Watch the complete research video观看完整研究视频2:58
Complete research video完整研究视频
2:58 · Full video完整视频
The full demonstration includes the method, simulation, one real task and 18 additional real examples. Experimental footage uses accelerated playback. Motion capture is used only to measure outcomes.完整演示包含方法、仿真、一段真实任务及另 18 个真实实验示例。实验片段采用加速播放,动作捕捉仅用于结果测量。
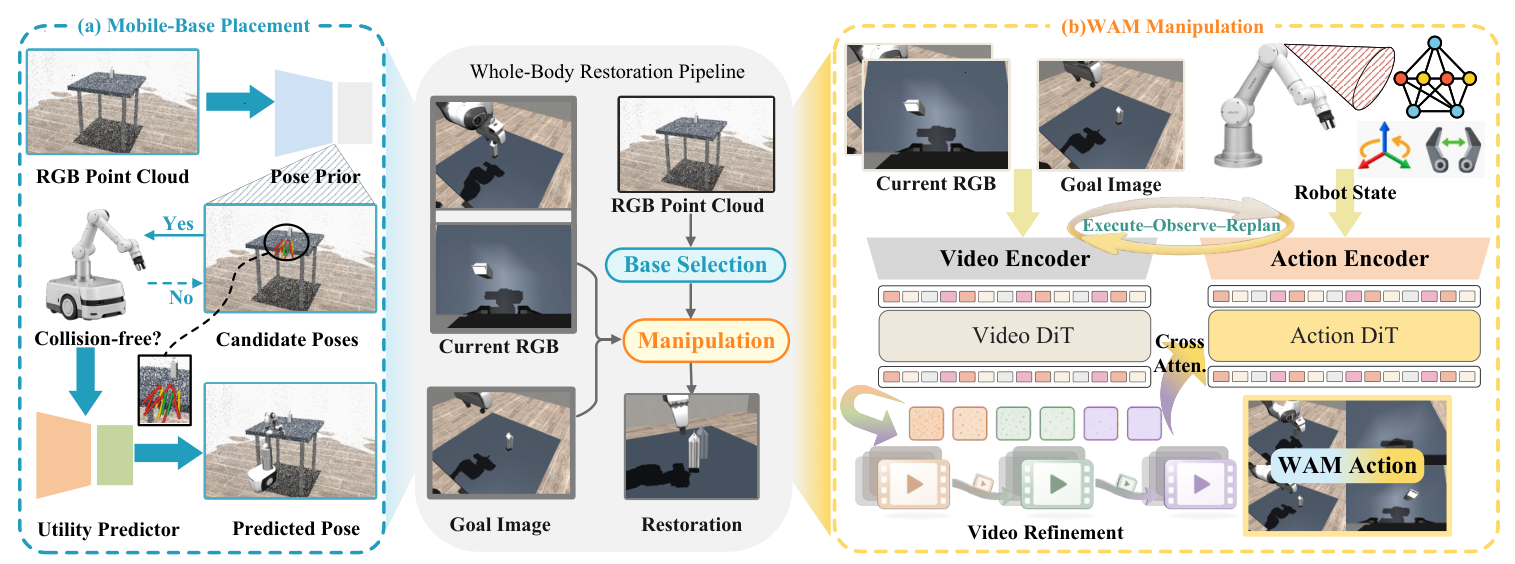
Base placement changes both the arm's starting state and camera viewpoint. Docking utility is therefore learned from restoration outcomes of a frozen WAM.底盘位置改变机械臂起始状态和相机视点。因此,停靠效用以冻结 WAM 的恢复结果为监督。
A coarse-to-fine execution pipeline: choose a docking pose, refine future-video predictions, generate actions, observe and replan.由粗到细的执行流程:选择停靠位置、细化未来视频预测、生成动作、重新观测并规划。Full-size figure查看原图
1
Dock for the task为任务选择停靠位置
Docking takes the current head-camera XYZ-RGB point cloud; the goal image conditions the subsequent WAM manipulation stage. A point-cloud pose prior proposes base poses. After collision filtering, prior and utility scores are combined to select a feasible pose. The utility predictor is trained on restoration outcomes from a frozen manipulation model.停靠模块输入当前头部相机的彩色点云;目标图像用于后续 WAM 操作。点云位姿先验提出候选底盘位置,经过碰撞过滤后,融合先验与效用评分选择可行停靠位姿。效用预测器以冻结操作模型的恢复结果为监督进行训练。
2
Refine future predictions细化未来预测
The default model refines its future video twice. Each call starts from fresh noise and conditions on the preceding prediction, while current camera observations and the visual goal stay fixed. New observations after physical action start the next planning round.默认对未来视频进行两轮细化。每轮从新的噪声开始,以前一轮预测作为条件;当前相机观测和视觉目标保持不变。实际动作执行后的新观测用于下一轮规划。
3
Execute, observe, replan执行、观测、重新规划
Only the final world features guide action generation. The robot executes the first 24 actions in the predicted sequence, then obtains new observations and plans again.仅将最终世界特征用于动作生成。机器人执行预测动作序列的前 24 步,随后获取新观测并再次规划。
02
Evidence for the design设计依据
The component study separates docking utility from future refinement. Its controls use three training seeds and the same 150 simulation cases per seed, with a 10 mm success threshold plus release and safety criteria.组件实验分别考察停靠效用与未来预测细化。对照使用三个训练种子,每个种子评估相同的 150 个仿真案例;成功需满足 10 mm 位置阈值,以及释放和安全条件。
Docking learned from manipulation outcomes以操作结果监督停靠选择
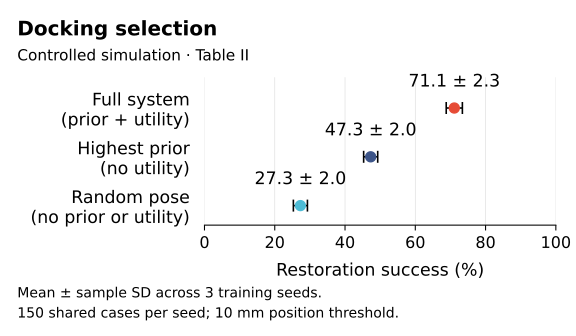
The WAM manipulation policy is frozen before docking utility is learned. Its complete restoration outcomes label candidate poses, so ranking reflects the manipulation that a pose enables. In Table II, removing utility scoring while retaining the same twelve candidates reduces mean success from 71.1% to 47.3%. This supports the outcome-based ranking within the reported benchmark; it is a staged docking-and-manipulation framework.WAM 操作策略在学习停靠效用之前被冻结,其完整恢复结果用于标记候选位姿,使排序反映该位姿下后续操作的表现。表 II 中,保留相同的十二个候选、但去除效用评分后,平均成功率由 71.1% 降至 47.3%。这支持所报告基准中的结果监督排序;方法仍是停靠与操作分阶段执行的框架。
Table II, manuscript p. 6. Mean ± sample SD across three seeds; each seed uses 150 fixed cases. All variants retain filtering, base control and WAM manipulation.稿件第 6 页表 II。均值 ± 三个种子的样本标准差;每个种子使用 150 个固定案例。各变体均保留候选过滤、底盘控制和 WAM 操作。Full-size figure查看原图
Recursive refinement under controlled denoising budgets去噪预算对照下的递归细化
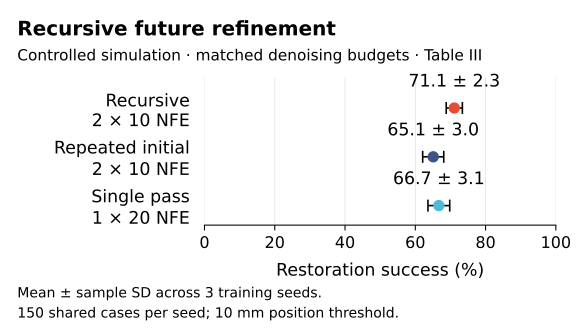
Two recursive calls condition on the latest predicted future and reach 71.1% mean success. The repeated-initial control reaches 65.1% and matches calls and per-call evaluations. One twenty-evaluation call reaches 66.7% and matches total denoising evaluations only. These are inference controls using the same checkpoint and action branch within each seed. The comparison supports recursive conditioning under this protocol, rather than simply more denoising evaluations.两轮递归调用均以前一轮预测为条件,平均成功率为 71.1%。两次均以初始未来为条件的对照为 65.1%,匹配调用次数和每次求值数;一次调用、二十次去噪求值的对照为 66.7%,仅匹配总去噪求值数。每个种子内,这些推理对照使用相同 checkpoint 和动作分支。结果支持该协议中的递归条件作用,而不只是增加去噪求值数。
Table III, manuscript p. 6. Error bars are sample SD across three seeds. Matched denoising budgets do not imply all computation is identical.稿件第 6 页表 III。误差线为三个种子的样本标准差。匹配去噪预算不等于全部计算完全相同。Full-size figure查看原图
A third recursive call increases mean success by only 0.2 percentage points, from 71.1% to 71.3%, while planning-round latency rises from 0.654 to 0.838 s on RTX 6000 Ada. The real Thor platform is reported separately at 1.326 s per default planning round. More refinement therefore has an explicit latency trade-off in the tested settings.第三轮递归仅使平均成功率增加 0.2 个百分点(71.1% 至 71.3%),同时 RTX 6000 Ada 上的规划轮时延由 0.654 s 增至 0.838 s。实机 Thor 的默认规划轮时延另为 1.326 s。增加细化深度在所测试设置中有明确的时延代价。
03
Measured restoration恢复实验结果
Position accuracy with explicit success criteria.以明确成功条件评估位置恢复精度。
Mean ± sample SD · all 30 trials均值 ± 样本标准差 · 全部 30 次
Success requires a safe release within the allowed budget, with the object resting on the task surface without gripper support and final position error ≤10 mm in simulation or ≤30 mm on the real robot. Reported errors include failed trials. Orientation is not evaluated.
150 fixed cases · main evaluation, Table I150 个固定案例 · 主实验,表 I
Method方法
ID success域内成功率
OOD success域外成功率
DP-GC
11.1%
1.7%
π₀.₅-GC
40.0%
20.0%
Hyper-GoalNet
8.9%
1.7%
WAM + Task-Level IC
64.4%
28.3%
Copy-Paste
77.8%
61.7%
Simulation ID covers three seen object types in six training-seen scene configurations, with 90 cases. OOD covers two held-out object types in three held-out configurations, with 60 cases. Table I reports these groups separately; the 71.1% in the component studies is mean success across three training seeds, each evaluated on the same 150 cases. The 10 mm threshold also requires release and safety criteria. Simulation and real-robot rates use different tolerances and settings.仿真 ID 为三类已见物体、六个训练中见过的场景配置,共 90 个案例;OOD 为两类未见物体、三个保留场景配置,共 60 个案例。表 I 分别报告这两组结果;组件实验的 71.1% 是三个训练种子在每个种子相同 150 个案例上的成功率均值。10 mm 阈值还需结合释放与安全条件。仿真和实机成功率使用不同容差与测试设置。
Real robot真实机器人
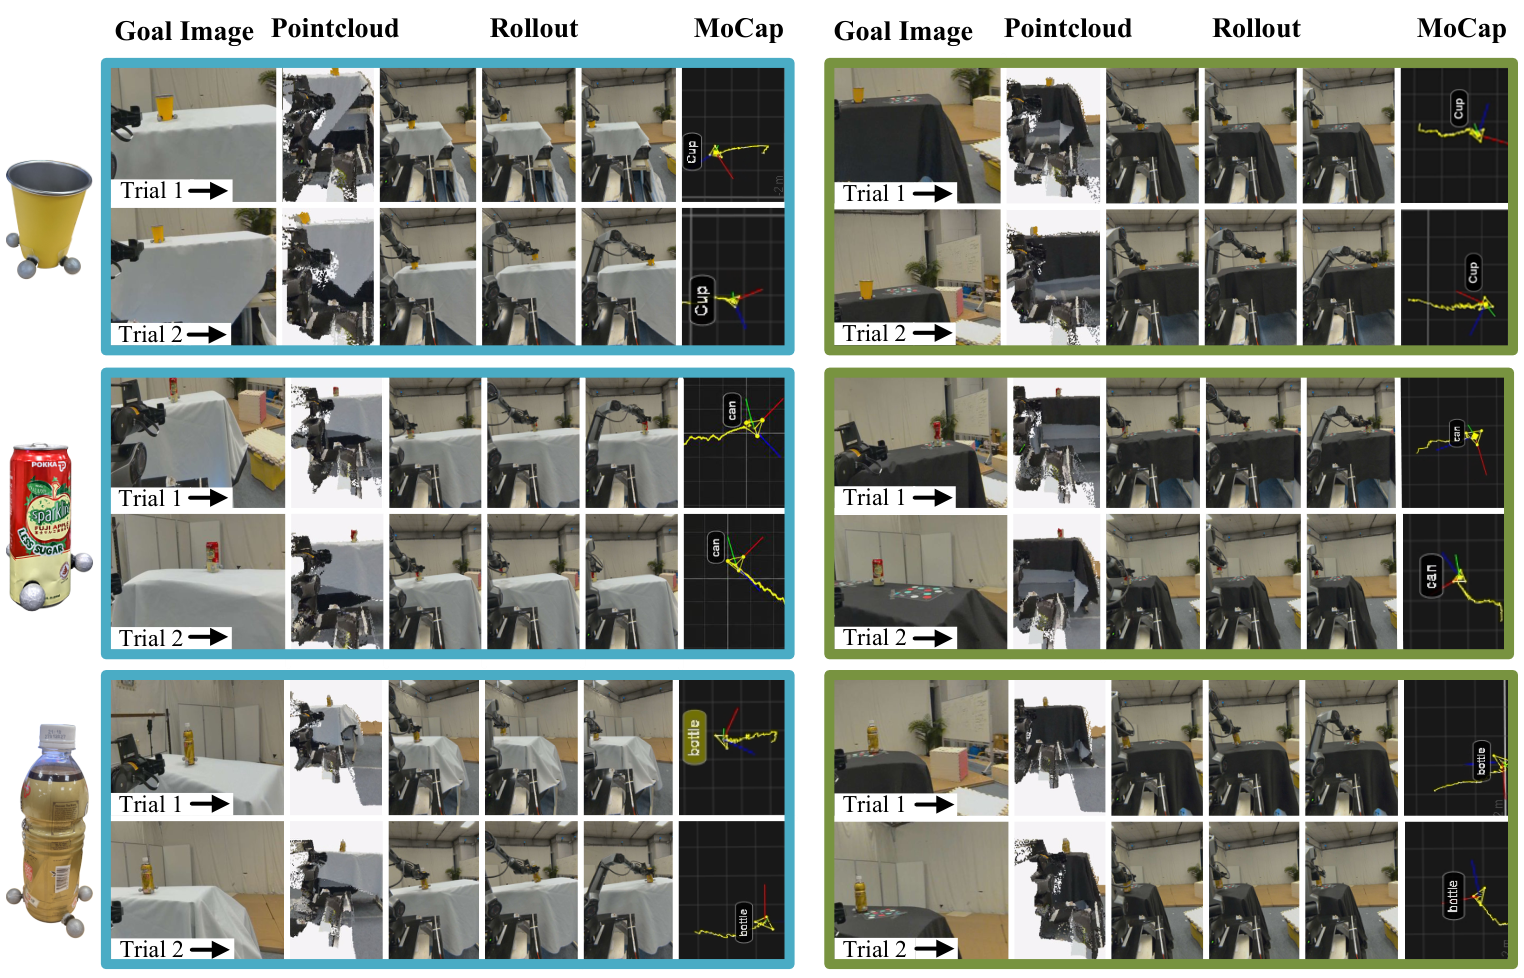
The real platform uses an AgileX Ranger Mini 3.0 base, a PiPER arm and a Jetson AGX Thor. Tests include a seen cup, held-out can and bottle, and seen/held-out tables. With two refinement rounds, the mean planning-round latency on Thor is 1.326 seconds.真实平台使用 AgileX Ranger Mini 3.0 底盘、PiPER 机械臂和 Jetson AGX Thor。测试涵盖见过的杯子、未见过的罐子与瓶子,以及见过和未见过的桌子。在 Thor 上,两轮细化配置每规划一轮的平均时延为 1.326 秒。
Twelve representative examples from 30 evaluated trials. Blue and green borders distinguish seen and held-out tables; motion capture is for evaluation only.从 30 次评估中选取的 12 个代表性示例。蓝色与绿色边框分别表示见过和未见过的桌子;动作捕捉仅用于评估。Full-size figure查看原图
04
Scope & limitations范围与局限
Evaluation measures restoration position. Object and scene coverage is limited, and robot vibration, arm-control noise and base errors can reduce precision. Refinement adds latency; a third round brings diminishing gains.实验衡量恢复位置。物体与场景覆盖范围有限,机器人振动、机械臂控制噪声及底盘误差会影响精度。细化带来额外时延,第三轮的增益较小。
Training uses 1,769 simulation trajectories and 600 real demonstrations.训练使用 1,769 条仿真轨迹和 600 条真实示范。
05
Conclusion结论
The reported experiments support docking supervised by manipulation outcomes and recursive future refinement before action generation. The real system completes 19 of 30 restorations within a 30 mm position tolerance. Refinement has a planning-latency cost, and performance remains limited by the tested objects, scenes and physical execution noise.所报告实验支持以操作结果监督停靠选择,并在动作生成前递归细化未来预测。实机系统在 30 mm 位置容差下完成 30 次恢复中的 19 次。细化需要额外规划时间,表现仍受测试物体、场景范围及真实执行噪声限制。